May Update: Latchkey Runners Are Live
April 2026: the runners beta reached production. Four sizes from $0.0025 a minute, plans with included minutes, and custom runners from a repo scan.
Kaveh Alemi
CTO, Latchkey
April was the month the runners stopped being a beta: small and medium reached production on April 19, large and xlarge followed on April 27, and any GitHub Actions job in a connected organization can now move to a Latchkey runner by changing one line. This update covers what is live, what it costs, the custom runners you can build from a scan of your repository, everything else that shipped in April, what is coming this month, and where we think the platform is going.
Platform core: one line, four sizes
The migration is the same one we described during the beta, and it is still the whole pitch:
# Before
runs-on: ubuntu-latest

# After
runs-on: latchkey-small
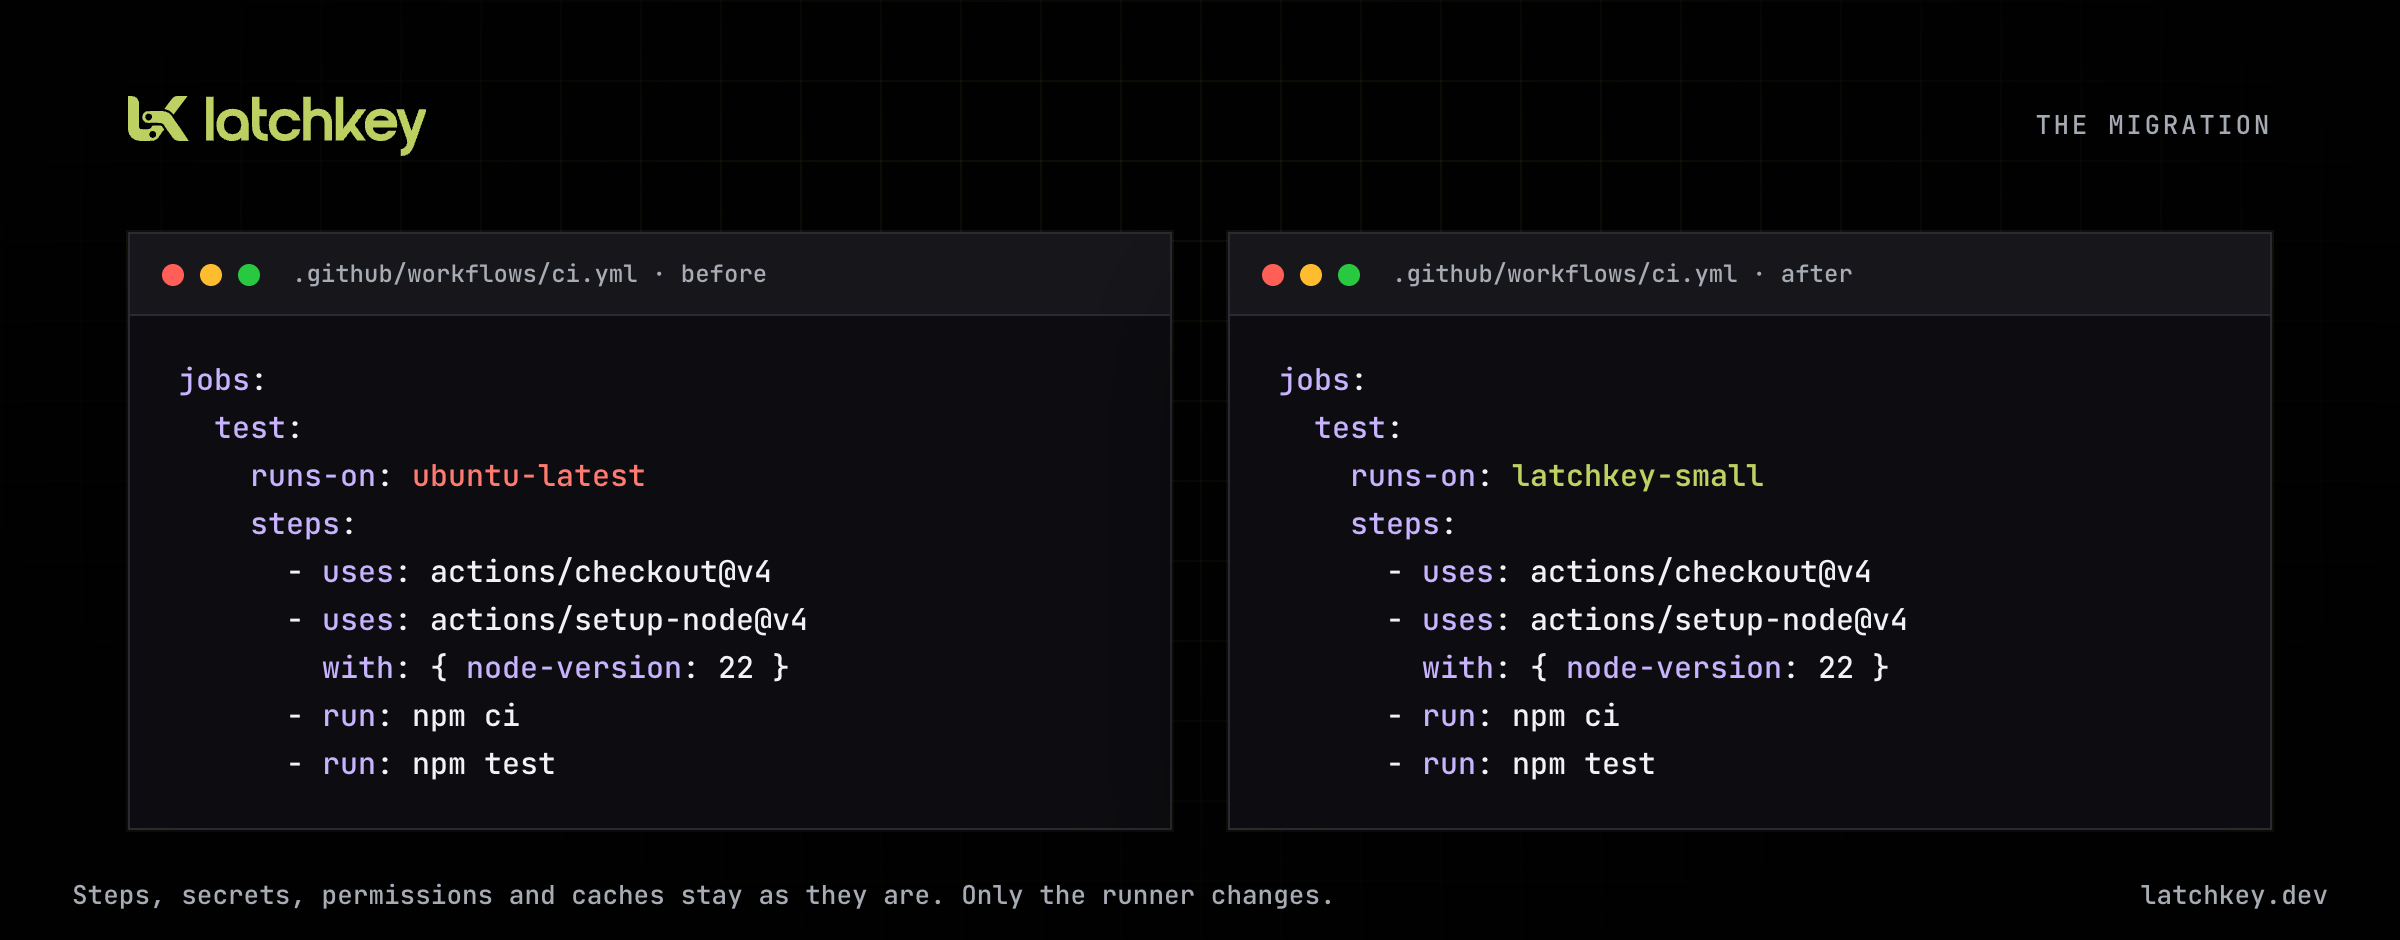
Your steps, secrets, permissions, matrix and actions/cache calls stay as they are. A Latchkey runner registers with GitHub like any self-hosted runner, so GitHub remains the orchestrator: it schedules the job, shows the logs and enforces your permissions. We supply the machine.
That matters because most of what teams complain about in CI is a runner problem, not a workflow problem. Machine size is fixed, so a lint job and a monorepo build get the same two cores. The environment drifts between image releases, and you find out when a build breaks. The same setup is paid for on every run. And cost is a single number, not a breakdown by repository, workflow or size. None of that is fixed by editing your workflow. It is fixed by changing what runs it.
As of May 1 there are four preset sizes, each a fresh Ubuntu 24.04 virtual machine that runs exactly one job and is then thrown away:
| Label | vCPU | Memory | Disk | Per minute |
|---|---|---|---|---|
latchkey-small |
2 | 8 GB | 100 GB | $0.0025 |
latchkey-medium |
4 | 16 GB | 100 GB | $0.005 |
latchkey-large |
8 | 32 GB | 100 GB | $0.01 |
latchkey-xlarge |
16 | 64 GB | 200 GB | $0.02 |
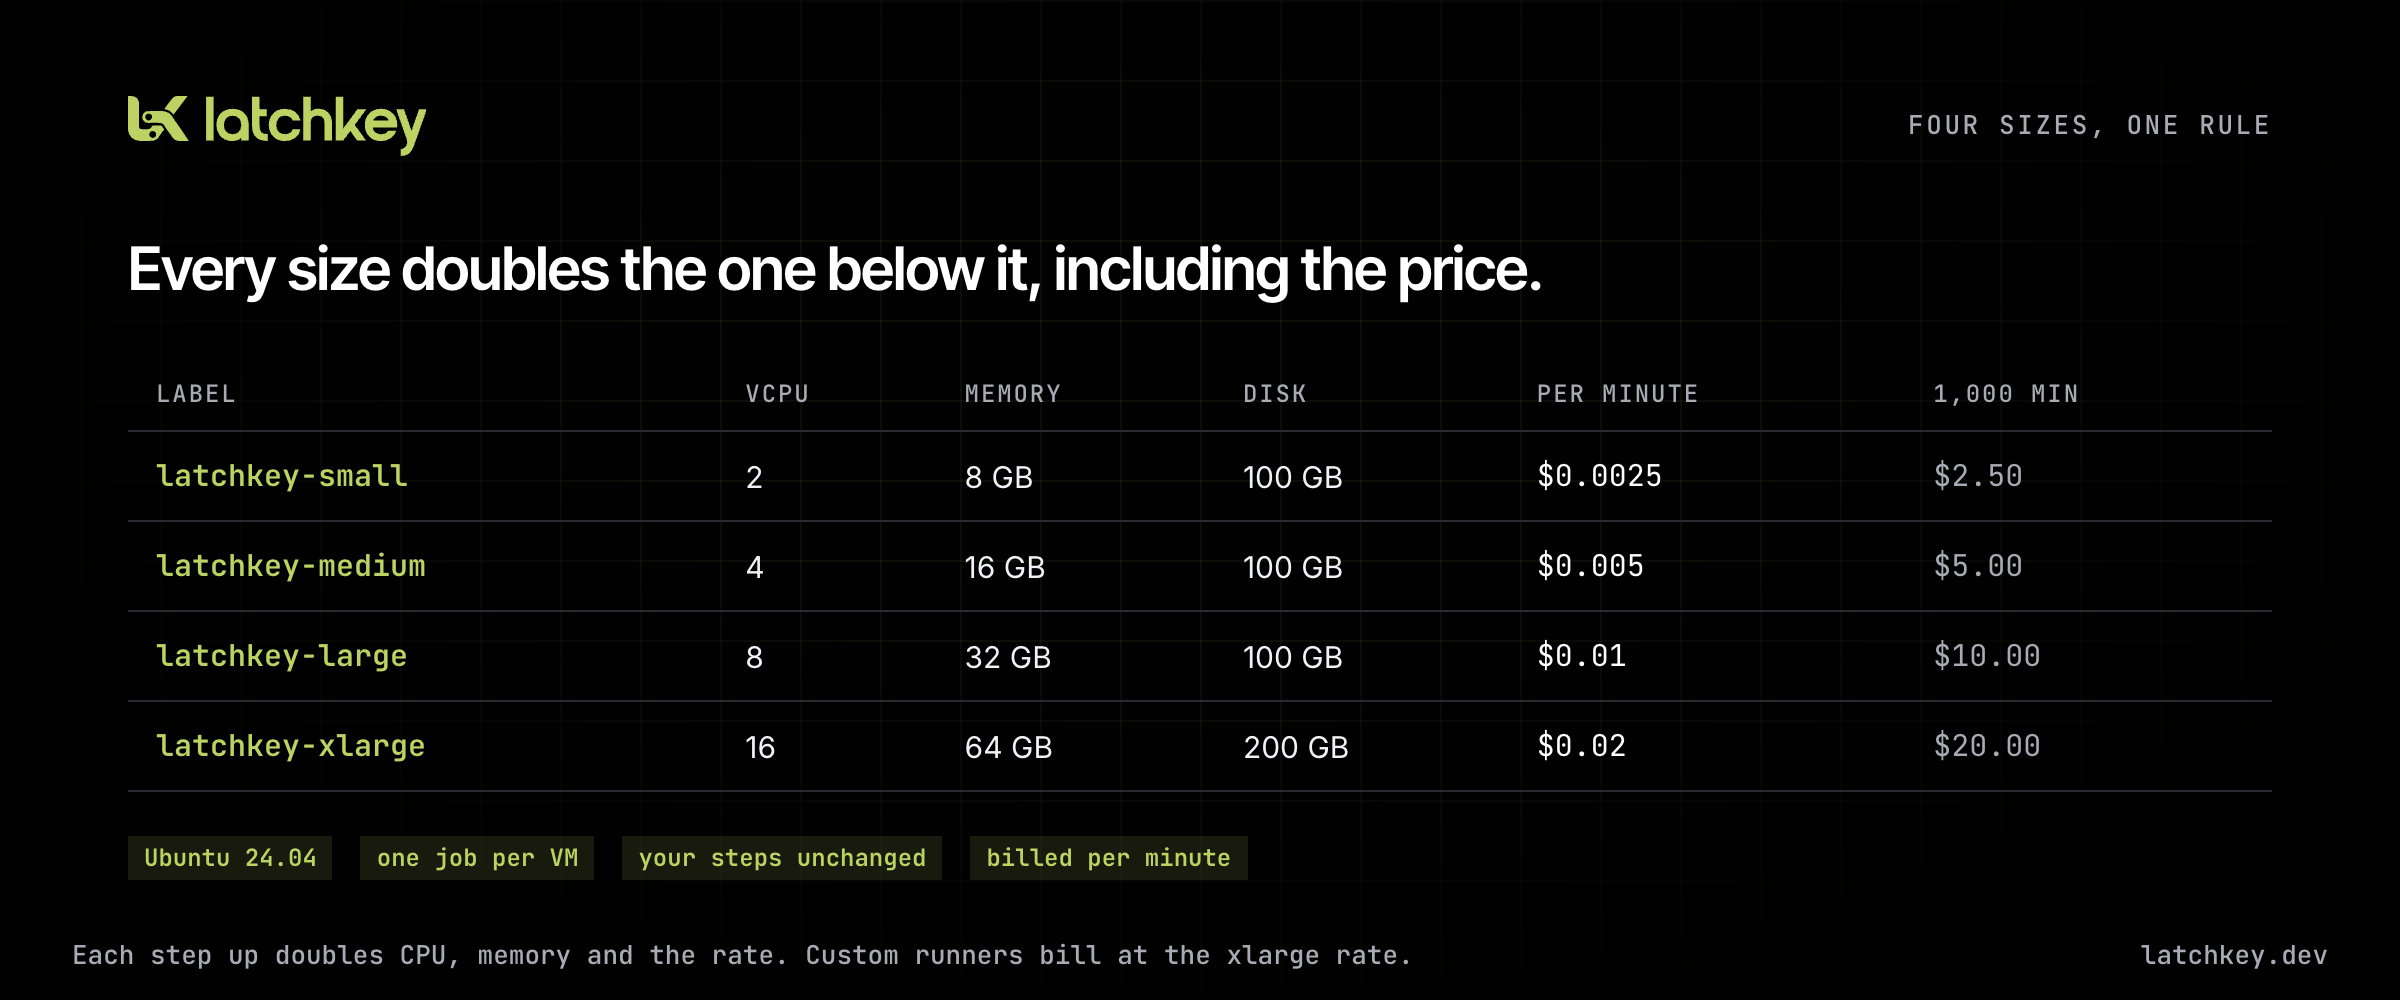
The rule is deliberately boring: each step up doubles CPU, memory and the rate. That turns the sizing decision into arithmetic. Moving a job from small to medium costs the same only if it finishes in half the time. A large TypeScript or Rust build often gets close to that; a lint job never will, so leave lint on small.
This is what the Runners page showed for the preset sizes at launch:
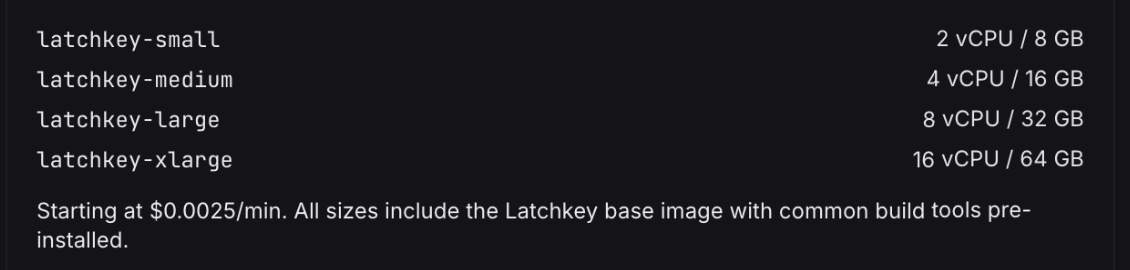
The preset sizes on the Runners page. Every size boots the same base image.
A few properties matter more than the table:
- One job, one machine. Nothing from a previous job, yours or anyone else's, is on the machine your job gets.
- Built to match the machine you already test on. The base image aims for parity with GitHub's own Ubuntu 24.04 runner: the same compilers, language runtimes, Docker with BuildKit, browsers and drivers, databases and common CLIs, in the places GitHub puts them. The
actions/setup-*actions find the preinstalled versions instead of downloading them. - Caching that works as written.
actions/cacheworks with no change, and the cache lives in the same region as the runner. Each organization's cache is isolated from every other organization's. - Faster starts on paid plans. Launch and Scale keep runners ready ahead of your jobs, so a busy repository does not wait for a machine to boot on every push. A job never depends on that: if no ready runner is free, it gets a fresh one.
We are not publishing a start-time number yet. We would rather measure it properly across sizes and regions than quote the best run we saw. When we have numbers we trust, they will be in this ledger with their method. And if something breaks on a Latchkey runner that works on GitHub's, that is a parity bug: tell us and we will fix it in the image rather than ask you to change your workflow.
To get going: install the Latchkey GitHub App on your organization (runners register at the organization level, so repositories need to live in one), turn on managed runners on the Runners page, change runs-on, and push. The jobs table shows which runner took each job.
Platform core: what it costs
Pricing went live with the runners on April 19:
| Plan | Price | Included runner minutes | Repositories |
|---|---|---|---|
| Developer | $5 / month | 2,000 | 1 |
| Launch | $19 / month | 4,000 | up to 10 |
| Scale | $49 / month | 6,000 | up to 40 |
Minutes beyond the included amount are metered per minute at the size's rate. The dashboard's cost page can be filtered by runner size, so you can see which size is using them.
On the comparison everyone asks for, here is the arithmetic with its basis. Our small runner is $0.0025 a minute for 2 vCPU. GitHub's list price for its standard 2-core Linux runner is $0.006 a minute after its January 1, 2026 price reduction. For 10,000 Linux minutes in a month at those rates, that is $25 against $60, before either side's included minutes and plan fees. That is a per-minute price comparison, not a promise about your bill: your bill depends on your job mix, which sizes you choose, and how long your jobs take on each. The cost page prices your actual jobs, and that is the comparison I would trust.
Platform core: custom runners, built from a scan
Preset sizes solve the machine. They do not solve the minute or two many jobs spend installing the same packages on every run. Custom runners do.
From the Runners page you pick a repository and start a scan:
- What your repository needs. An AI agent reads your workflows, package manifests, Dockerfiles and build scripts, and comes back with your tech stack, a recommended size and a list of what your jobs install: a Python version,
ffmpeg, the Playwright browsers, a pinned Node release. Anything the base image already covers is marked as such and skipped. - What would change in your workflows. For each workflow, a proposed rewrite:
runs-onmoves to your new label, setup steps the image now covers are removed, caching is added where it helps, and anything the agent is not sure about is left exactly as it was. Every change is labelled with what it did and why. - Your approval. Nothing is built and nothing touches your repository until you approve.
- The image. We build a runner image on top of the base image with your packages installed, your runtime versions pinned, the Docker images you use preloaded and your environment variables set.
- A pull request. When the image is ready, we open one pull request on your repository with a table of what changed in each workflow, and which ones were skipped and why. Merging it is your call, and until you do, your CI runs exactly as before.
The label is yours to choose, as long as it looks like latchkey-<name> and does not collide with a preset:
runs-on: latchkey-api-tests
When your dependencies change, you rescan. The rescan updates the existing configuration in place, so the label your workflows use never changes.
Launch includes 2 custom configurations and Scale includes 10. Custom runners bill at the xlarge rate, $0.02 a minute, whatever size they run on. We chose one flat rate over a price per machine type so there is no second price list to reason about. The tradeoff is real: a custom runner on a small machine costs more per minute than the preset it replaced, and it pays off only when the install time it saves outweighs that. For a job that spends two minutes on setup and one on tests, it usually does. For a job that installs nothing, stay on a preset.
Coming next
Self-healing CI. This month we intend to start fixing CI failures for you, on the runner, while the job is still running: a missing system package, a flaky network fetch, a cache that should be rebuilt. The principles are fixed before any of it ships. We repair the environment, never your code. A failing test that catches a real bug is doing its job and stays red. Any change an automated fix makes to files is fenced to CI and configuration paths, and anything that should outlive a single run arrives as a pull request you review. We will report what it actually does once there are numbers to report.
Web Summit Vancouver, May 11–14. We will have a booth. If you run GitHub Actions and have opinions about runners, flaky builds or what CI should look like when agents write most of the code, come and find us. Bring a workflow file you are unhappy with and we will read it with you. If you want to be sure of catching us, reach us through the Support page and we will set a time.
Platform vision: the runner is where CI learns to act
Since the first issue, our bet has been that CI has to act, not only report. For most of Latchkey's life we could only do the second. We read your runs after they finished, priced them, diagnosed them and proposed fixes as pull requests. That covered the lower rungs of the trust ladder from February's issue: observe, recommend, change things through a PR you review. The rung we had not reached was acting inside a running job, because the job ran on a machine we did not control.
April changes that. The runners are a product in their own right, and they have to be one: cheaper per minute, boring to size, identical to what you already test on, so that moving is not a gamble. But the reason we built them is what they make possible. When the machine is ours, for exactly one job, we can repair its environment at the moment a step fails and throw the machine away afterwards, so a fix can never leak into the next job.
The pressure behind this keeps growing. More of the code reaching CI is written by agents, faster than people can watch red builds. The pipeline becomes the gate between machine output and your main branch, and a gate that waits for a human every time a runner is missing a tool slows down the whole loop. We think CI in the agent era needs to handle the environment on its own and hand real failures back clearly, to a person or their agent. The rules do not bend to get there. Acting inside a job is the rung that has to be earned, on the record of everything below it.
Previous issue: April Update: The Runners Beta Opens · Next issue: June Update: Self-Healing CI Is On by Default